// THE LAB / MARKETING EXPERIMENT PREFLIGHT
How I Pressure-Test Marketing Experiments Before Media Spend
How much time does your team spend deciding what to A/B test before the A/B test even starts?
Meetings about the test. Slack threads about the meeting. Three headline options nobody loves. Then somebody says, “Let’s test all of them,” which is corporate for “we still have not made a decision.”
I built this private marketing and revenue lab to make the cheap decisions before the expensive test begins. It brings the campaign, audience, current version, challenger, evidence, economics, measurement plan, and sales capacity into one record. AI can challenge the setup. Deterministic code checks the math and the rules. The market still gets the final vote.
The public example is a five-channel revenue decision
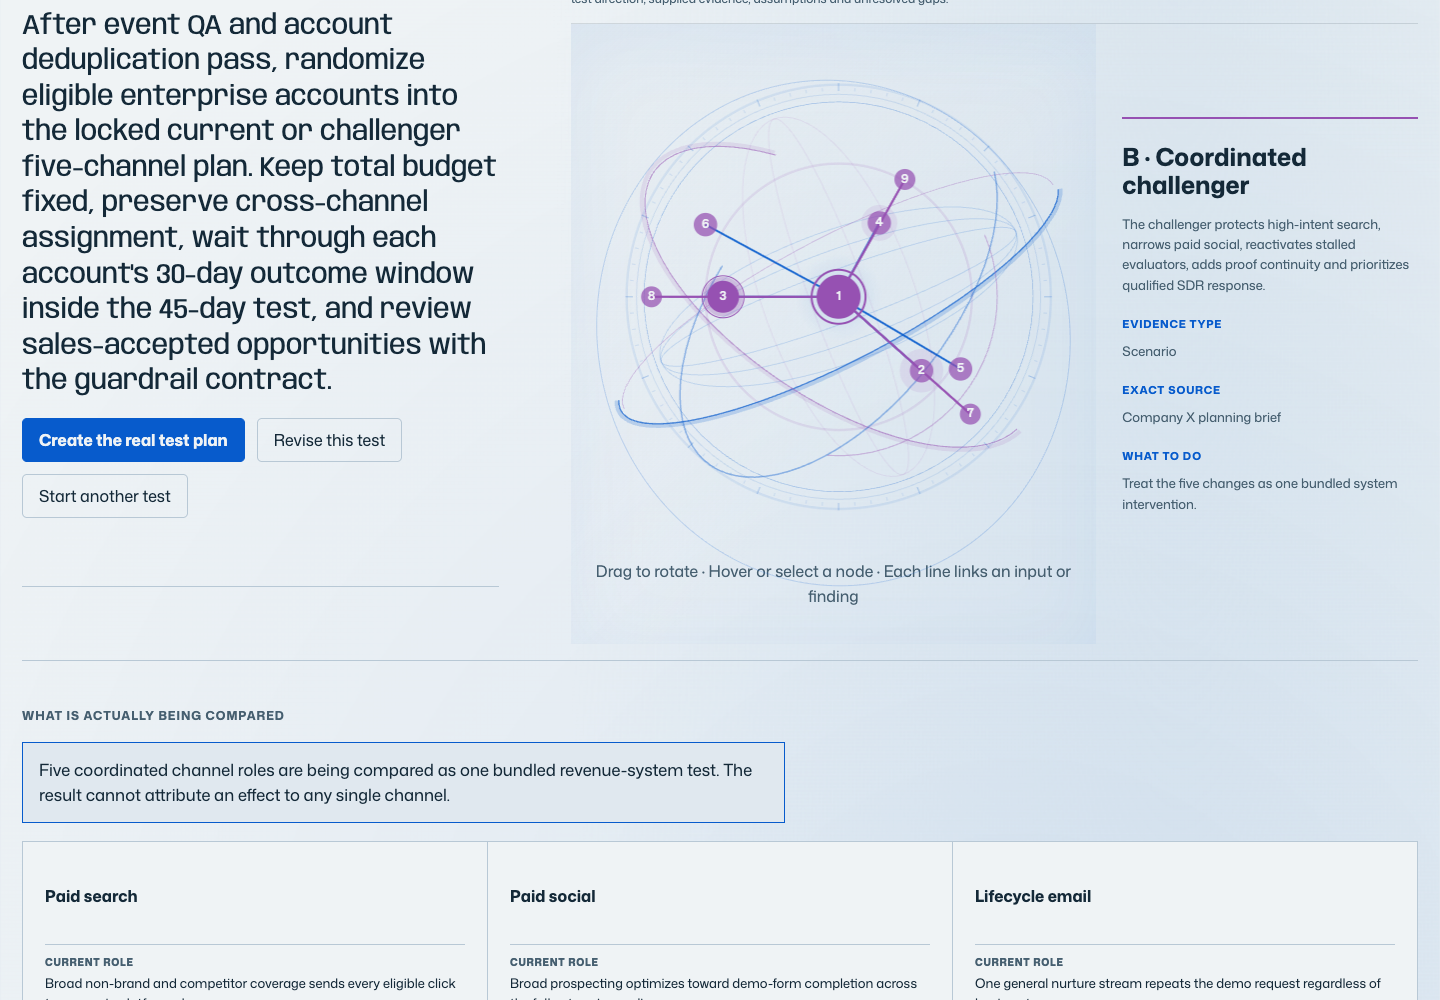
The walkthrough asks whether fictional Company X should test a coordinated proof-first journey for stalled enterprise pipeline before moving its limited demand-generation budget. The control and challenger span paid search, paid social, lifecycle email, the landing page, and SDR follow-up.
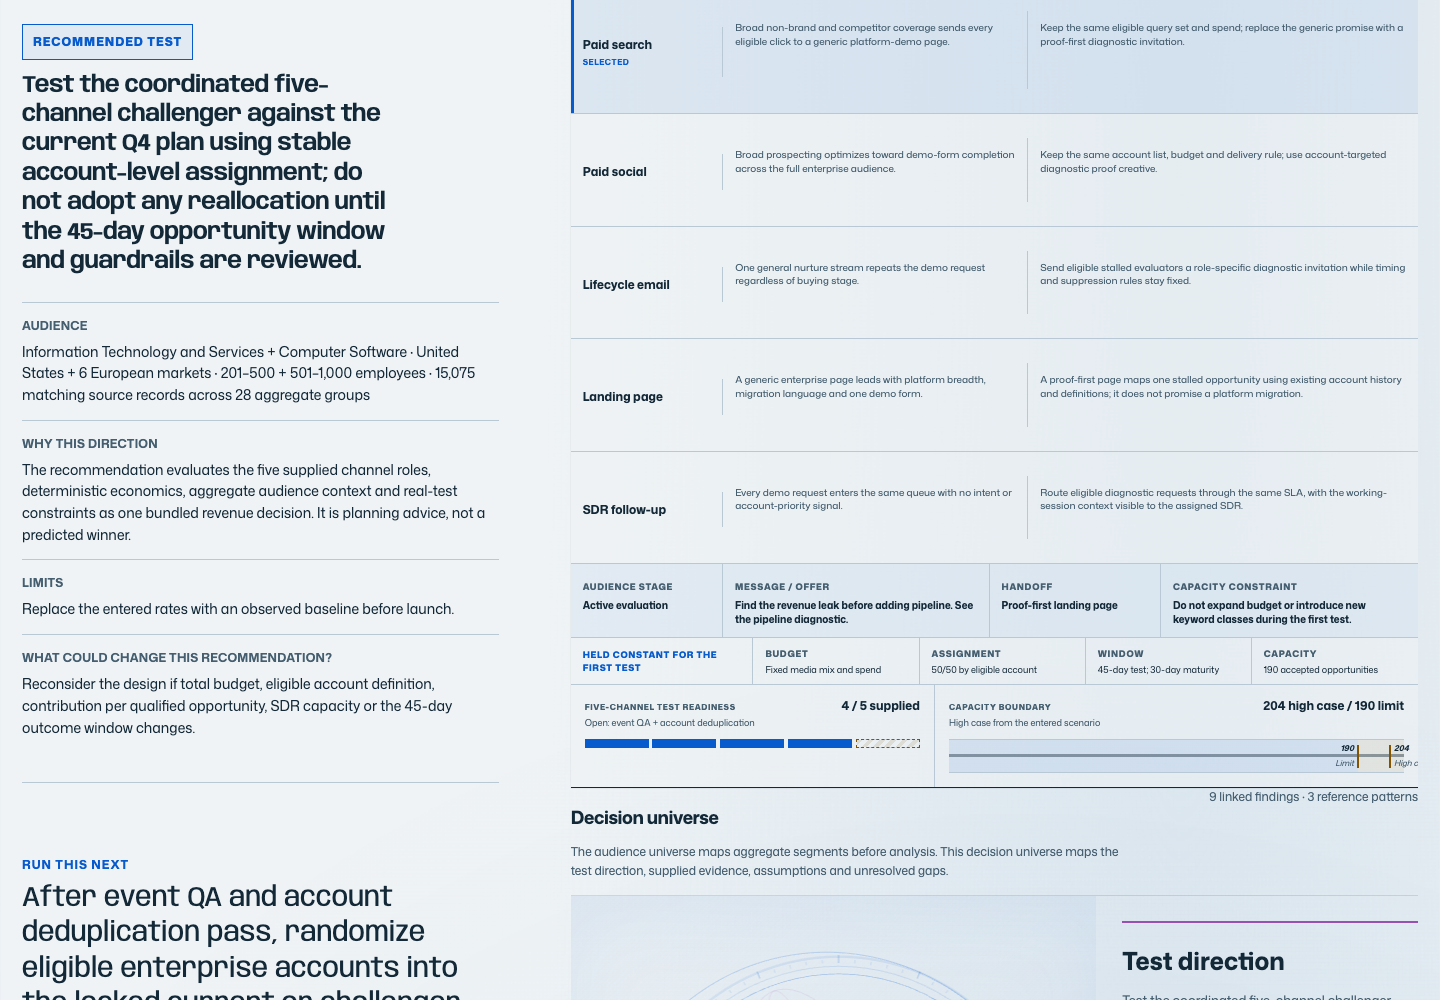
The current journey sends broad traffic to a generic demo page, optimizes social toward form completion, repeats the same demo request by email, uses broad platform language on the page, and sends every response into the same SDR queue. The challenger keeps the budget and eligible account set fixed while changing the promise, proof, role-specific follow-up, landing-page handoff, and SDR context as one coordinated system.
This is intentionally harder than a headline-versus-headline demo. A cleaner sentence does not prove a better revenue motion. The useful question is whether the ad, page, lifecycle message, sales handoff, measurement contract, and operating capacity support the same decision.
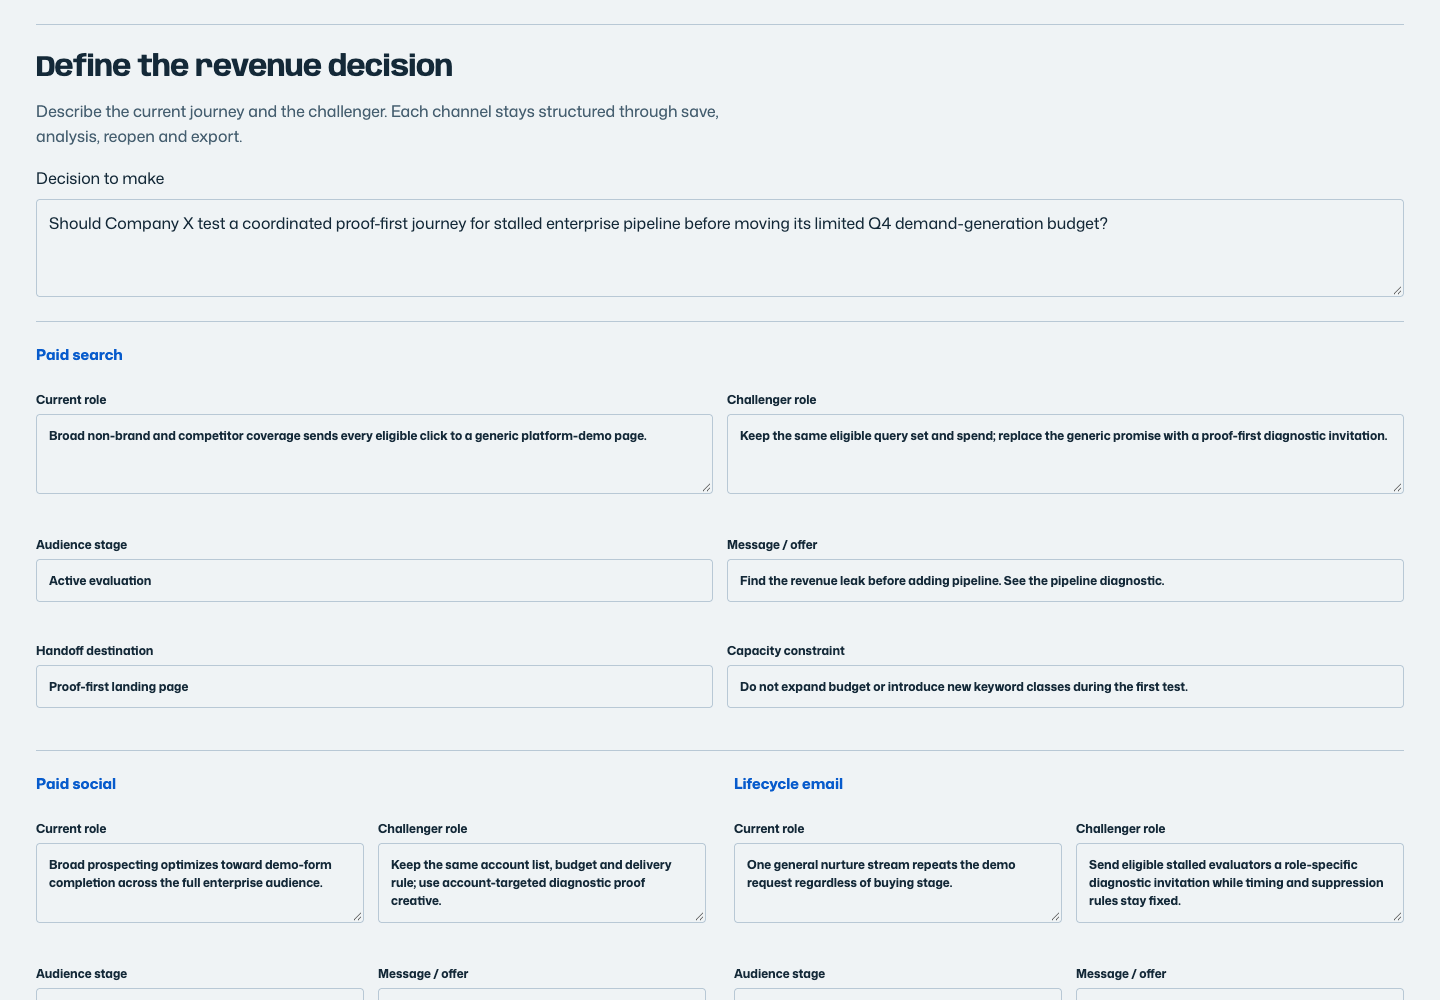
What is marketing experiment preflight?
Marketing experiment preflight is the work of defining the audience, control, challenger, evidence, economics, capacity, outcome, and stopping rule before traffic or media spend enters a test. It gives a team one decision that can be evaluated, then exposes the defects that would make the answer expensive and useless.
A useful preflight asks simple questions that become expensive when nobody asks them:
- What changes between control and challenger?
- Who sees each version, and how do we know the groups are comparable?
- What exact outcome matters, over what period, and with what denominator?
- What evidence is observed, modeled, synthetic, stale, or missing?
- When does the test stop, and who decides what happens next?
That sounds basic because it is. The work gets difficult when the answer lives across an ad account, an analytics tool, a CRM, a finance system, a spreadsheet, and the memory of the person who set up the campaign. The lab is my attempt to keep those decisions from dissolving the moment the campaign starts.
Why I built a private marketing and revenue lab
Marketing has a memory problem. A team can spend real money testing a landing page, an offer, an audience, a sales sequence, or an onboarding flow. A few weeks later, the result is reduced to a sentence in Slack: “That did not work.” The original version is gone. The alternative is gone. The source data is stale. The metric changed. Nobody remembers whether the audience changed with the creative.
That is how the same question gets bought twice.
The first version of this lab is a place to preserve the decision itself. A record can hold the original asset, a proposed alternative, the audience context, the evidence attached to the decision, the intended outcome, the test constraints, and a human-recorded outcome when one exists. It can be reopened later with a timestamp cutoff so the team can inspect what was known before a result was available.
Hindsight makes every result look obvious. A decision record lets you see the actual evidence, uncertainty, and assumptions that were available at the time.
What is in the build today
The working lab takes a marketing or revenue decision from a loose idea to a reviewable test packet. It holds the audience definition, current system, challenger, evidence, assignment rule, outcome, economics, capacity limit, guardrail, and owner together instead of scattering them across a deck, spreadsheet, CRM field, and meeting transcript.
| Current capability | What it does | What to inspect |
|---|---|---|
| Aggregate audience context | Organizes 35,892,370 company-profile source records into 117,341 groups by industry, country, and company size. | Whether the eligible audience is defined precisely enough to test. |
| Five-channel comparison | Compares the current and challenger roles across paid search, paid social, lifecycle email, landing page, and SDR follow-up. | Whether the messages, handoffs, and outcome support one coherent test. |
| AI challenge layer | Reviews the supplied material, identifies conflicts, proposes stronger directions, and names evidence that could change the recommendation. | Advice that still requires a person to decide what enters the test. |
| Deterministic scenario engine | Calculates traffic, rates, cost, contribution, break-even, and capacity from explicit inputs. | The exact assumption carrying each planning case. |
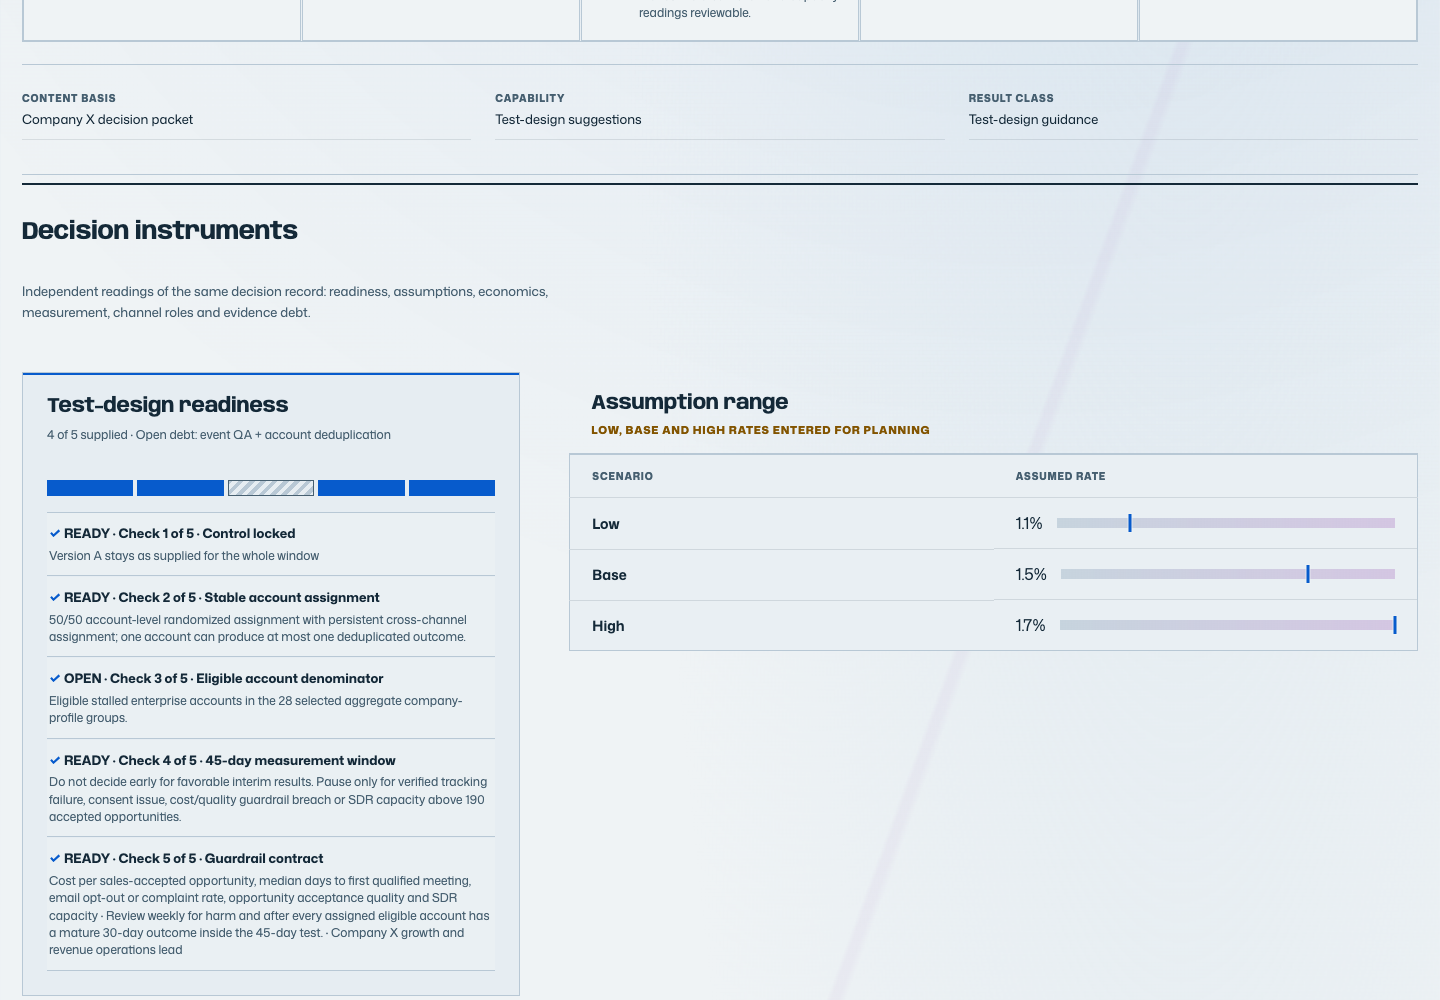
| Readiness checks | Checks the control, challenger, assignment, denominator, outcome window, stopping rule, guardrail, and owner. | Which missing definition should hold the test before launch. |
| Decision record and replay | Freezes the supplied inputs, evidence, analysis, and method information, then appends later outcomes without rewriting the original decision. | What the team knew when it made the call and what arrived later. |
The public Company X packet narrows the audience to 15,075 source records across 28 aggregate groups. The underlying company-profile snapshot was captured in September 2026. The ingestion scan excluded 1,006 malformed rows rather than coercing them into the index, and the source did not supply a reliable freshness timestamp. The globe lets me inspect the industry, country, company size, and record count behind the label. It is an interface for understanding the audience definition, not a map of individual people or predicted response.
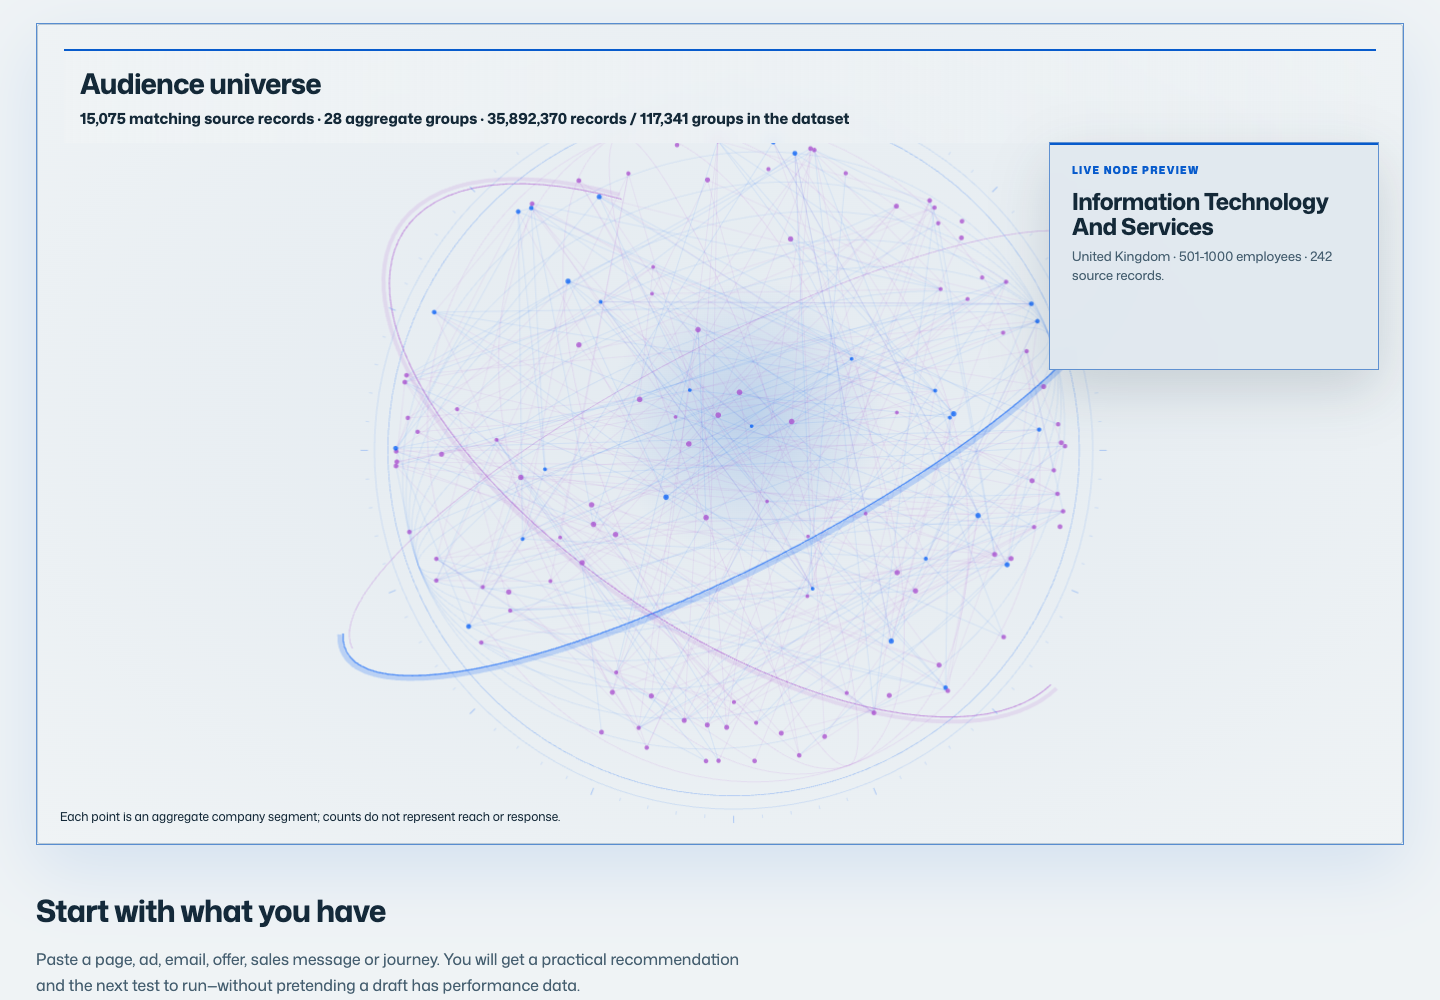
How the build handles evidence
The lab distinguishes six evidence categories: observed, modeled, synthetic, assumed, benchmark, and unknown. An assumption about conversion rate needs a different label from a measured conversion rate.
| Evidence state | Meaning in the lab |
|---|---|
| Observed | A real outcome from an admitted source, with its period, unit, and definition attached. Observed outcomes enter only after the real test is complete. |
| Modeled | Deterministic what-if math or model advice. Useful for deciding what to test. It is never measured response. |
| Synthetic | A fictional fixture or rehearsal used to test whether the machinery behaves as intended. It does not prove lift. |
| Assumed | An input chosen for planning that has not been established by observation. It needs to stay visible when the scenario changes. |
| Benchmark | A reference value used for comparison. Its source and relevance need review before applying it to this experiment. |
| Unknown | A missing, unauthorized, stale, or unverified fact. Unknown stays visible. It does not quietly become zero. |
A model can propose a sharper question, identify a missing definition, or point out a control problem. The system allows winner language only when the evidence is classified as an observed causal outcome and includes its source, period, denominator, and outcome definition. The output-safety layer filters unqualified winner, lift, revenue-impact, and customer-response language from generated recommendations. That guard is not evidence of campaign performance. A person still has to admit the outcome and its evidence. A private source should never turn into a public claim.
That boundary follows the same principle I use in my work on AI connector governance: a system may inspect evidence for a defined job, but the evidence does not get to expand the system's authority. Connecting a source and trusting a source are different decisions.
How the lab works under the hood
The lab separates language judgment from repeatable calculation. It runs as a private web application built with plain HTML, CSS, JavaScript modules, and a Node runtime. I can trace a number from the field that supplied it to the calculation that used it and the result displayed on screen.
AI handles ambiguity
It compares the current and challenger systems, spots conflicts, proposes stronger test directions, and explains which missing evidence could change the recommendation.
Code handles the math
Traffic, assumed rates, cost, contribution, break-even, capacity, and readiness run through deterministic functions. The same inputs return the same numbers.
Evidence carries provenance
Every value can carry a class, source, period, unit, freshness, availability, and relevance. Conflicting evidence stays visible instead of being averaged into false certainty.
A person owns the release
The system can recommend TEST, HOLD, or ABSTAIN. It cannot launch media, change a bid, update a CRM record, or turn planning advice into an observed result.
Before a test can proceed, code checks its control, challenger, assignment rule, eligible denominator, outcome window, stopping rule, tracking declaration, guardrail and owner. The Test Before the A/B Test explains why those definitions belong before launch. If the operator changes an input, the earlier analysis becomes invalid and must be run again. That prevents an old answer from sitting beside new assumptions.
The Company X scenario uses a 45-day fictional window. Its planning range includes 144 accepted opportunities at baseline, break-even at 162, a base challenger case of 180, and a high case of 204 against operating capacity for 190. Those numbers are entered assumptions, not a forecast. Their job is to expose that the high planning case would outrun Sales before anyone increases the budget.
I also built a synthetic truth test because statistical language can look convincing long before a method has earned trust. The test plants known conditions in fictional data, locks the hypothesis and measurement boundary before the hidden condition is revealed, then checks whether the method sees the direction it was designed to detect. The saved prediction record includes a SHA-256 hash, which lets me check whether its definition changed after the reveal.
The method sandbox includes CausalPy synthetic-control checks, Spotify Confidence as an A/B analysis reference, and separate synthetic allocation work with Ax, Optuna, and Nevergrad. Those are engineering checks, not live campaign optimization. No visitor traffic is allocated. No customer outcome is reported.
What a preflight can catch before media spend
The lab is more useful when it catches a bad question than when it produces a polished recommendation. Here are the failure modes I want it to expose early:
- Control drift. The creative, audience, offer, landing page, and follow-up all change at once. A result cannot tell you which change mattered.
- An undefined outcome. Different systems can count different events. “More leads” is not a metric. A test needs a counted event, denominator, window, and owner.
- A missing stopping rule. Somebody will want to stop when the chart looks good or bad. Decide the threshold and the time window before the first click arrives.
- An evidence gap hidden as confidence. The source is stale, the audience match is loose, or the CRM definition is disputed. The right answer may be to collect a fact before testing.
- A decision nobody can reconstruct. If a later team cannot see the version, the audience, the evidence, and the assumptions, it cannot use the result responsibly.
How the learning loop preserves what the team knew
Each saved decision freezes the version, inputs, assumptions, evidence, analysis, and method information available at that moment. Saving is explicit. Nothing autosaves, and the lab does not learn automatically from campaign activity. A later outcome is appended by a person with its source, unit, period, action, and caveats. It does not rewrite the original decision.
A timestamp cutoff can replay what was available when the call was made without refitting an old counterfactual. A separate local backtest sandbox can fit a calibration on rows before a defined cutoff and evaluate later held-out rows; it measures held-out fit, not causal lift. The source receives a SHA-256 fingerprint so the lab can detect whether the input changed after the answer was visible. Unknown rows remain unknown instead of quietly becoming zero.
That produces a practical learning loop: frame the decision, lock the comparison, run the real test, append the outcome, and bring the record forward when a later decision is genuinely comparable. Similarity is context, not proof. A past result may come from a different market, offer, period, channel mix, or sales motion, and the record should make that difference obvious.
A better system should never let one source overwrite another because the dashboard needs a clean answer. The ad platform should remain authoritative for delivery. Analytics should remain authoritative for behavior. The CRM should remain authoritative for lifecycle stage. Finance should remain authoritative for recognized revenue and margin. When those values disagree, the decision record needs to keep the conflict visible and name the owner who resolves it.
Where the lab can expand across MarTech, RevOps, and sales
The same record format applies far beyond a landing-page test. The object is always the same: a decision, its evidence, its constraints, its authority boundary, and the outcome that eventually earns a place in the record.
| Commercial team | A preflight question | What a stronger future record would connect |
|---|---|---|
| Marketing | Should this message, offer, audience, or page be tested, and what would a fair comparison require? | Campaign delivery, creative version, click identifiers, consent state, page and CTA version, and defined conversion events. |
| RevOps | Do the lifecycle definition, attribution window, and handoff rules make this result usable? | Analytics behavior, CRM stage history, routing rules, qualification definitions, and offline outcome reconciliation. |
| Sales | What should change in this outreach, discovery, offer, or onboarding motion, and what evidence would show it helped? | Approved account context, message version, meeting or opportunity stage, human review, and an owned outcome period. |
| Leadership | Which assumptions are carrying the commercial plan, and what would change the spend decision? | Scenario inputs, capacity limits, pipeline definitions, finance-owned revenue and margin, and the decision owner. |
There is a sharper future version of this same machinery for account-based work. A connector could frame a preflight around one named company and its public footprint, so the first conversation begins with a specific, inspectable commercial question instead of a generic pitch. The decision record does not change. Only the permitted context does, and that remains a connector decision with a defined source, scope, and owner.
I am intentionally keeping future activation out of the first connector plan. The lab can prepare a better question before it should be allowed to change a bid, update a CRM record, enroll a contact, or publish a claim. Read, review, and write are different jobs. That boundary is the subject of my AI governance work for commercial teams.
How connectors strengthen the decision record
Planned source definitions cover PageSpeed Insights and Chrome UX Report, Google Search Console, Google Analytics 4, Bing Webmaster Tools, Google Ads Keyword Planner, Google Ads reporting, and Meta Marketing Ads Insights. These are planned read-only integrations, each with a specific question to answer. They are not connected live sources.
A source contract defines the fields, freshness expectation, owner, retention boundary, and approval path before the data can influence a recommendation. The point is not to collect every number available. It is to admit the smallest set of evidence that could change the decision.
Search, site quality, paid media, CRM, and finance answer different questions:
- Search and site quality: Which query, page, and experience signals could change how a landing-page hypothesis is framed?
- Paid media: Which delivery, keyword, creative, and cost signals belong beside a proposed audience and offer test?
- Revenue operations: Which lifecycle and qualification facts need a shared definition before marketing can claim a campaign influenced pipeline?
- Finance: Which revenue and margin facts should be attached before anyone says a commercial motion paid back?
Read, review, and write remain separate authorities. A source can inform the test packet without receiving permission to change a bid, launch a campaign, enroll a contact, update a CRM record, or publish a claim. That boundary is the practical connection between experiment design and AI connector governance.
What I will share, and what will stay private
I am not opening the application as a public demo. The lab holds private work, internal source details, and experimental machinery that does not belong behind a public URL. I will share the useful parts: the data model, sanitized screenshots, short walkthroughs, failure cases, connector decisions, and the actual lessons that survive contact with real outcomes.
Every public result will say whether its evidence is observed, modeled, synthetic, or unknown. If I connect a source, I will say what it is allowed to do. If an assumption changes, I will update the decision record instead of rewriting history. The goal is a system that gets more useful because it can be inspected, challenged, and repaired.
That is also the common thread with Brokaw Bets. In football, a number only becomes useful when the player, matchup, source, and time context stay attached. Commercial data has the same problem. The hard part is rarely finding another number. It is keeping the decision context intact long enough for the number to matter.
Frequently asked questions
What is marketing experiment preflight?
Marketing experiment preflight is the work of defining the audience, control, challenger, evidence, outcome, and stopping rule before traffic or media spend enters a test. It does not predict a winner. It makes a test question specific enough to answer and exposes defects that would otherwise waste budget.
How does the marketing experiment preflight lab work?
The lab combines aggregate audience context, a current and challenger system, evidence notes, deterministic scenario math, readiness checks, capacity constraints, and an owned measurement plan in one decision record. The record can later append an outcome without rewriting what the team knew before launch.
Which parts of the lab use AI?
AI compares the current and challenger systems, spots conflicts, proposes stronger test directions, and explains what evidence could change the recommendation. Deterministic code handles traffic, rates, cost, contribution, break-even, capacity, readiness, and state. A person decides what enters a real test.
How are the scenario numbers calculated?
Scenario numbers come from explicit traffic, rate, cost, contribution, break-even, and capacity inputs processed by deterministic functions. The same inputs return the same numbers. Low, base, and high values are planning cases, not a probability distribution or a forecast.
How does the lab distinguish modeled, synthetic, and observed evidence?
The lab uses six categories. Observed evidence has a source and period. Modeled evidence is scenario math or model advice. Synthetic evidence uses fictional inputs to test mechanics. Assumed evidence is a planning input awaiting verification. Benchmark evidence supplies a reference comparison. Unknown marks a missing or unverified fact. A benchmark or assumption does not become an observed result.
How does the lab preserve a marketing learning loop?
A saved decision freezes the version, inputs, assumptions, evidence, analysis, and method information available at that moment. Later outcomes are appended with their source, unit, period, action, and caveats. Timestamp-cutoff replay shows what the team knew before the outcome arrived.
How can the same system support MarTech, RevOps, and sales?
The same decision record can evaluate campaigns and landing pages in marketing, lifecycle and attribution definitions in RevOps, and outreach, handoff, or onboarding hypotheses in sales. Each use keeps the decision, evidence, constraints, owner, and eventual outcome together.
Build status
Current private build: aggregate audience context, five-channel decision packets, AI challenge and recommendation, deterministic scenario math, readiness checks, evidence provenance, capacity checks, timestamp-cutoff replay, and outcome entry. The public example uses fictional Company X inputs so the technical workflow can be shown without exposing private work.
About the author
Jeff Brokaw is a CMO and Certified Chief AI Officer who builds commercial systems around AI, data, measurement, and the decisions that make those systems useful. He has been building AI systems commercially since 2016.